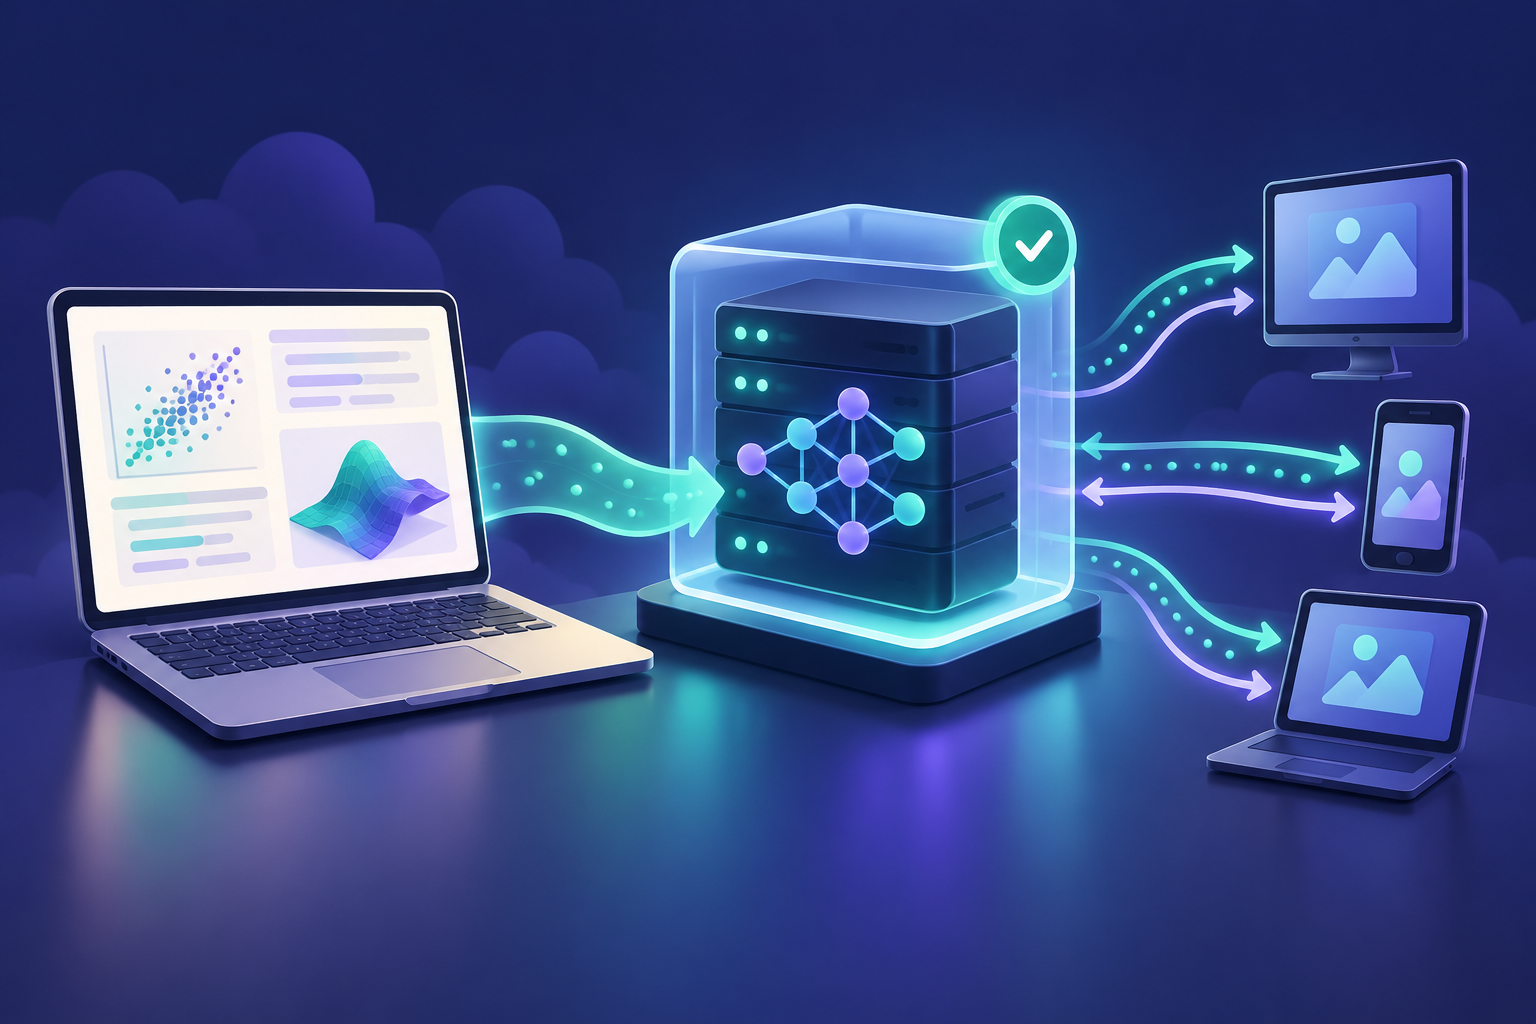
A notebook is a good place to explore data. It is not, by itself, a reliable interface for another application. To make a model usable by a client, package its expected inputs and preprocessing with the prediction logic, then expose a small, validated API.
This example uses FastAPI and a scikit-learn pipeline. It focuses on the handoff between training and serving; it is not a complete production deployment recipe.
If the training process imputes missing values, scales features, and then predicts, the service must apply the same steps in the same order. Save the pipeline rather than saving only the final estimator:
import joblib
from sklearn.impute import SimpleImputer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

pipeline = make_pipeline(
    SimpleImputer(strategy="median"),
    StandardScaler(),
    LogisticRegression(max_iter=1000),
)
pipeline.fit(X_train, y_train)
joblib.dump(pipeline, "artifacts/completion-model.joblib")
Keep the feature order, training data version, code revision, and dependency versions with the artifact. Only load model files from a trusted source. Python object serialization formats such as pickle and joblib can execute code during loading, so an uploaded or otherwise untrusted artifact is not safe to load.
An API request should state what fields the service expects. A schema can reject missing or malformed values before they reach the model:
from pydantic import BaseModel, Field

class CompletionRequest(BaseModel):
    lessons_started: int = Field(ge=0)
    days_since_enrollment: int = Field(ge=0)
    weekly_sessions: float = Field(ge=0)
This contract is part of the model interface. If the model expects a particular feature order or units, document them. A field called weekly_sessions should not quietly switch from a count of sessions to hours spent studying.
Load the trusted artifact once when the application starts, construct a dataframe with the exact training feature names, and return a response with a stable shape:
import joblib
import pandas as pd
from fastapi import FastAPI, HTTPException

app = FastAPI(title="Course Completion Prediction API")
model = joblib.load("artifacts/completion-model.joblib")

@app.get("/health")
def health():
    return {"status": "ok"}

@app.post("/predict")
def predict(request: CompletionRequest):
    try:
        row = pd.DataFrame([request.model_dump()])
        probability = float(model.predict_proba(row)[0, 1])
        return {"completion_probability": probability}
    except (ValueError, KeyError) as exc:
        raise HTTPException(status_code=422, detail="Input could not be processed") from exc
The code is a teaching example. In a real service, confirm that the response name and probability are meaningful for the model, handle only the errors you expect, and log useful diagnostic details on the server without exposing private user data in responses.
Before deployment, send a known row through both the training pipeline and the API path. The results should match within an expected tolerance. Check valid input, missing fields, invalid types, boundary values, and a case with missing data if the pipeline claims to support it.
Also check that the service and training code use the same transformation and feature order. A model can load successfully while receiving the wrong columns. Prefer sharing a versioned preprocessing pipeline over reimplementing preprocessing in a second code path.
The happy-path prediction is only one part of a usable endpoint. Decide what happens when:
Add request IDs and structured logs, but avoid logging raw request bodies by default. Provide a health check that reports whether the service can accept traffic, and a separate readiness check if model loading or warm-up takes time. Use authentication and rate limits when the endpoint is not intended to be public.
Deployment details depend on the hosting environment. HTTPS, startup behavior, restarts, process count, memory limits, and pre-start tasks all affect how an API behaves once it leaves a laptop. Test the artifact in an environment close to the target runtime, including the same Python and library versions.
Return or log a model version with each prediction so an issue can be tied to the code and artifact that produced it. Keep a rollback path to the previous working version. Once users depend on the service, monitor latency, request failures, and input quality in addition to model metrics.
The goal is not to turn a short notebook into a large platform. It is to make the model’s inputs, transformations, and serving behavior explicit enough that another system can use it predictably.
You might also be interested in reading these related topics