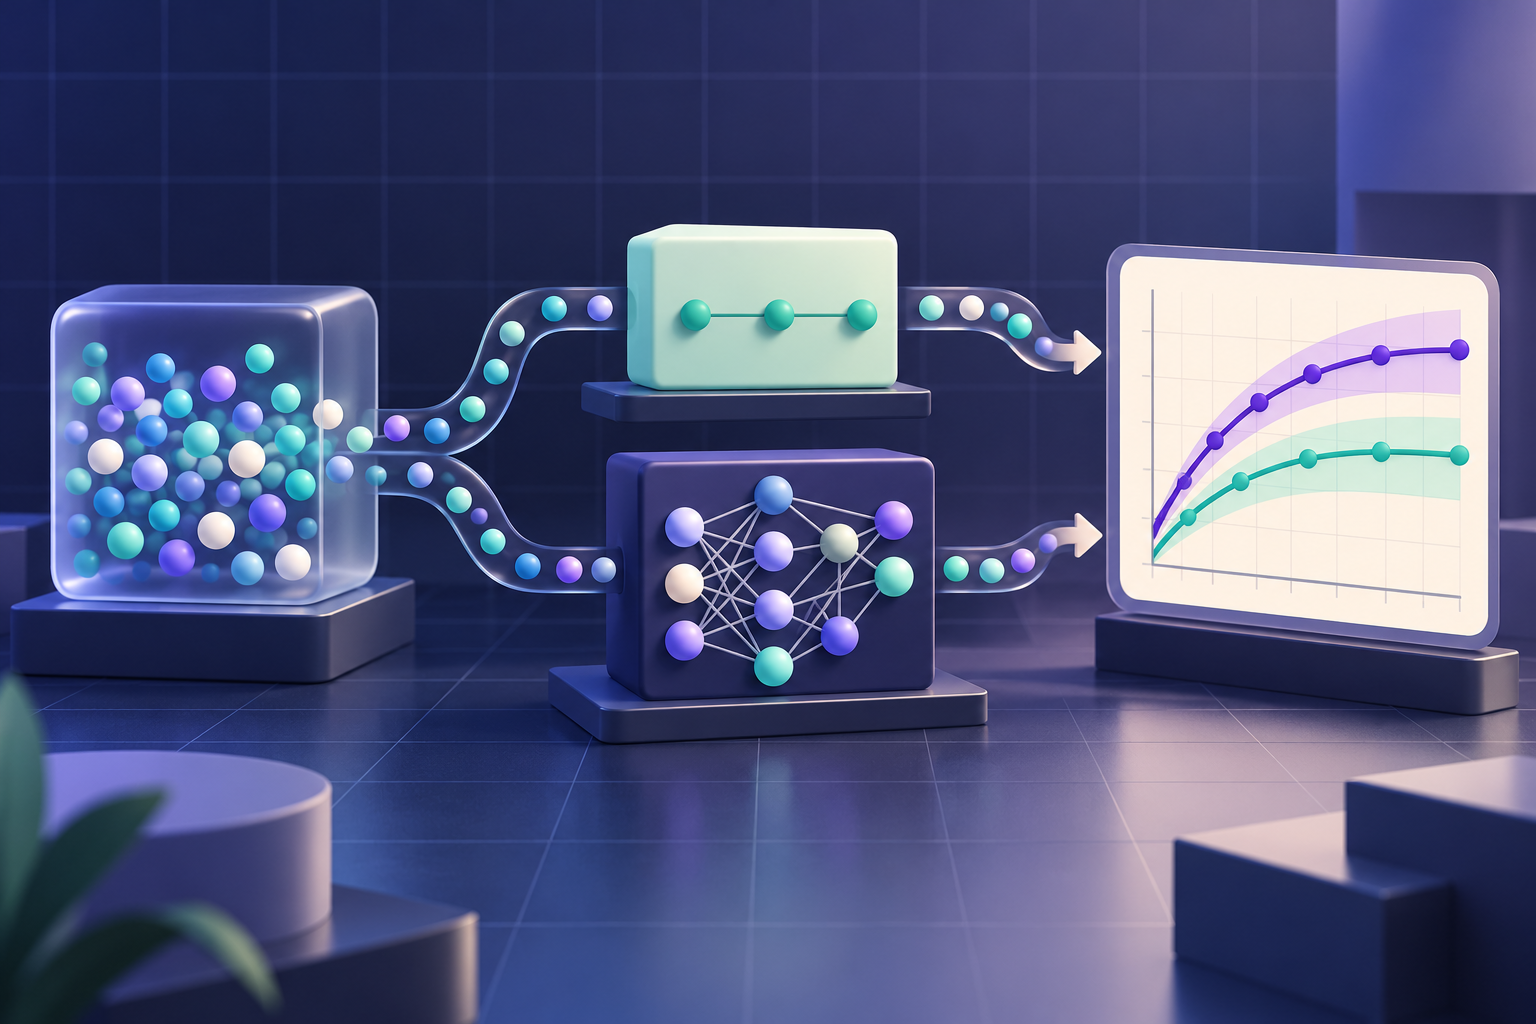
Before tuning a model, make sure you can answer a simpler question: what would a reasonable, uncomplicated approach do on this task? A baseline gives you a reference point. It also exposes problems in the data, metric, or task definition before you spend time on a larger model.
Consider a small project that predicts whether a learner will complete a course. The aim here is not to build a universal prediction system. It is to show a disciplined workflow that makes the result explainable and repeatable.
Start with the decision the prediction is meant to support. “Predict course completion” is incomplete until you specify:
These choices define the target and the information the model may use. If the prediction is made after the first week, features such as first-week activity may be available. A final completion timestamp is not. Using information created after the prediction moment gives the model a shortcut that will not exist when it is used.
Write the prediction moment down before selecting features. That single habit catches many misleading projects.
First, compare against a simple rule. If the positive class is rare, a model that predicts “not completed” for everyone may achieve high accuracy while being useless. That makes a majority-class baseline a useful warning, not a good final system.
For a binary classification task, DummyClassifier can establish that reference:
from sklearn.dummy import DummyClassifier
from sklearn.metrics import classification_report
from sklearn.model_selection import train_test_split

X_train, X_test, y_train, y_test = train_test_split(
    X, y,
    test_size=0.2,
    random_state=42,
    stratify=y,
)

baseline = DummyClassifier(strategy="most_frequent")
baseline.fit(X_train, y_train)
predictions = baseline.predict(X_test)

print(classification_report(y_test, predictions, zero_division=0))
This baseline answers: “How much does a naive class-frequency rule accomplish?” It does not answer whether the project is valuable. Choose the next baseline to match the data: a logistic regression for a transparent tabular comparison, a seasonal rule for a time series, or a simple keyword rule for a text task.
Keep a final test set separate from model selection. Any step that learns from data—imputation, scaling, feature selection, or dimensionality reduction—must be fit using training data only. Otherwise, information from the test set can leak into the model and make the evaluation look better than it should.
For tabular data, a scikit-learn pipeline keeps preprocessing attached to the estimator:
from sklearn.impute import SimpleImputer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

model = make_pipeline(
    SimpleImputer(strategy="median"),
    StandardScaler(),
    LogisticRegression(max_iter=1000, class_weight="balanced"),
)
model.fit(X_train, y_train)
Use a split strategy that matches how the model will encounter new examples. Random splits can be misleading when the same people, devices, or organizations appear in both train and test sets. If the real task predicts future outcomes, a time-based split may be more faithful. Keep related records together when a group-based split is needed.
Accuracy is easy to explain, but it can hide poor performance on a rare class. Look at precision and recall when the cost of false alarms differs from the cost of missed cases. Use a confusion matrix to count the two kinds of error. If you need a threshold-independent view of ranking, add a curve-based metric appropriate to the class balance.
There is no universally best metric. A team deciding who should receive a limited support call may care about precision at a fixed number of calls. A safety filter may care more about recall, with a second review step to manage false positives. Choose the metric before comparing candidate models, and record why it reflects the real decision.
After evaluating the baseline, create a small table of incorrect predictions. Include the original features that are safe to inspect, the true label, predicted label, and predicted probability if available. Then group errors by meaningful slices, such as course length or enrollment month.
The goal is not to find a story in every mistake. Look for a repeatable failure pattern:
Treat each pattern as a hypothesis. For example: “The model misses learners who start slowly because the training data contains few examples with low first-week activity.” Decide what evidence would support that explanation, then test one change at a time.
Save the data version, split method, random seed, preprocessing steps, metric definition, and model configuration. Include a short README that answers the original task questions and explains what the model cannot conclude. A clean project is more useful than a chart with an impressive score and no way to reproduce it.
Move to a more complex model only when you can describe what the baseline gets wrong and why the added complexity might help. If a simple baseline performs unexpectedly well, inspect for leakage and verify the split. If it performs poorly, determine whether the labels, features, and metric represent the task before trying a larger algorithm.
The baseline is not a hurdle to rush past. It is the control that makes every later experiment more informative.
You might also be interested in reading these related topics