Traditional unit tests often compare a function’s output with an exact expected value. That works well for deterministic code. It is less useful when a language model can express the same correct answer in several ways or when its output changes slightly across runs.
An evaluation suite solves a different problem: it checks whether an AI feature behaves acceptably across a representative set of cases. It does not replace ordinary software tests. It adds a repeatable way to compare prompts, models, retrieval settings, and tool workflows.
Avoid beginning with “Is this answer good?” Write down the behavior that matters to the user. For a study assistant, that could mean:
These expectations become criteria. Some can be checked by ordinary code. Others require a person or a model-assisted grader.
Each test case should contain enough information to reproduce the task:
{
  "id": "lesson-paraphrase-01",
  "input": "Explain the idea from the lesson without using its original wording.",
  "context": "The relevant lesson excerpt goes here.",
  "expected_behavior": [
    "Uses the supplied excerpt",
    "Explains the idea in new wording",
    "Does not introduce unsupported facts"
  ],
  "tags": ["paraphrase", "grounded-answer"]
}
Use examples from real tasks where possible, after removing personal or sensitive data. Add normal cases, edge cases, and cases where the system should decline or ask a follow-up question. Keep a held-out set for final comparisons if you are iterating frequently on prompts; otherwise the prompt can become tailored to a small fixture that does not resemble new requests.
Do not store only a “golden answer” and require an exact string match. Save a reference answer when it helps a reviewer, but define what a successful answer must do.
Apply checks in layers:
For example, if a response must contain three quiz questions, validate the count with code. If it must not invent facts outside a lesson, a simple keyword rule is unlikely to be sufficient; use human review or a carefully designed grader and periodically compare the grader with human judgments.
If you use a model to grade another model, give it a bounded question rather than a vague instruction to assign a quality score. A useful rubric might ask whether the answer is supported by the supplied evidence, with labels such as supported, partially_supported, or unsupported, and require a short rationale that points to the relevant text.
Test the grader itself. Provide examples where it should pass and fail, and compare its decisions with human review. A grader can share the same blind spots as the system under test. Treat its output as evidence, not ground truth.
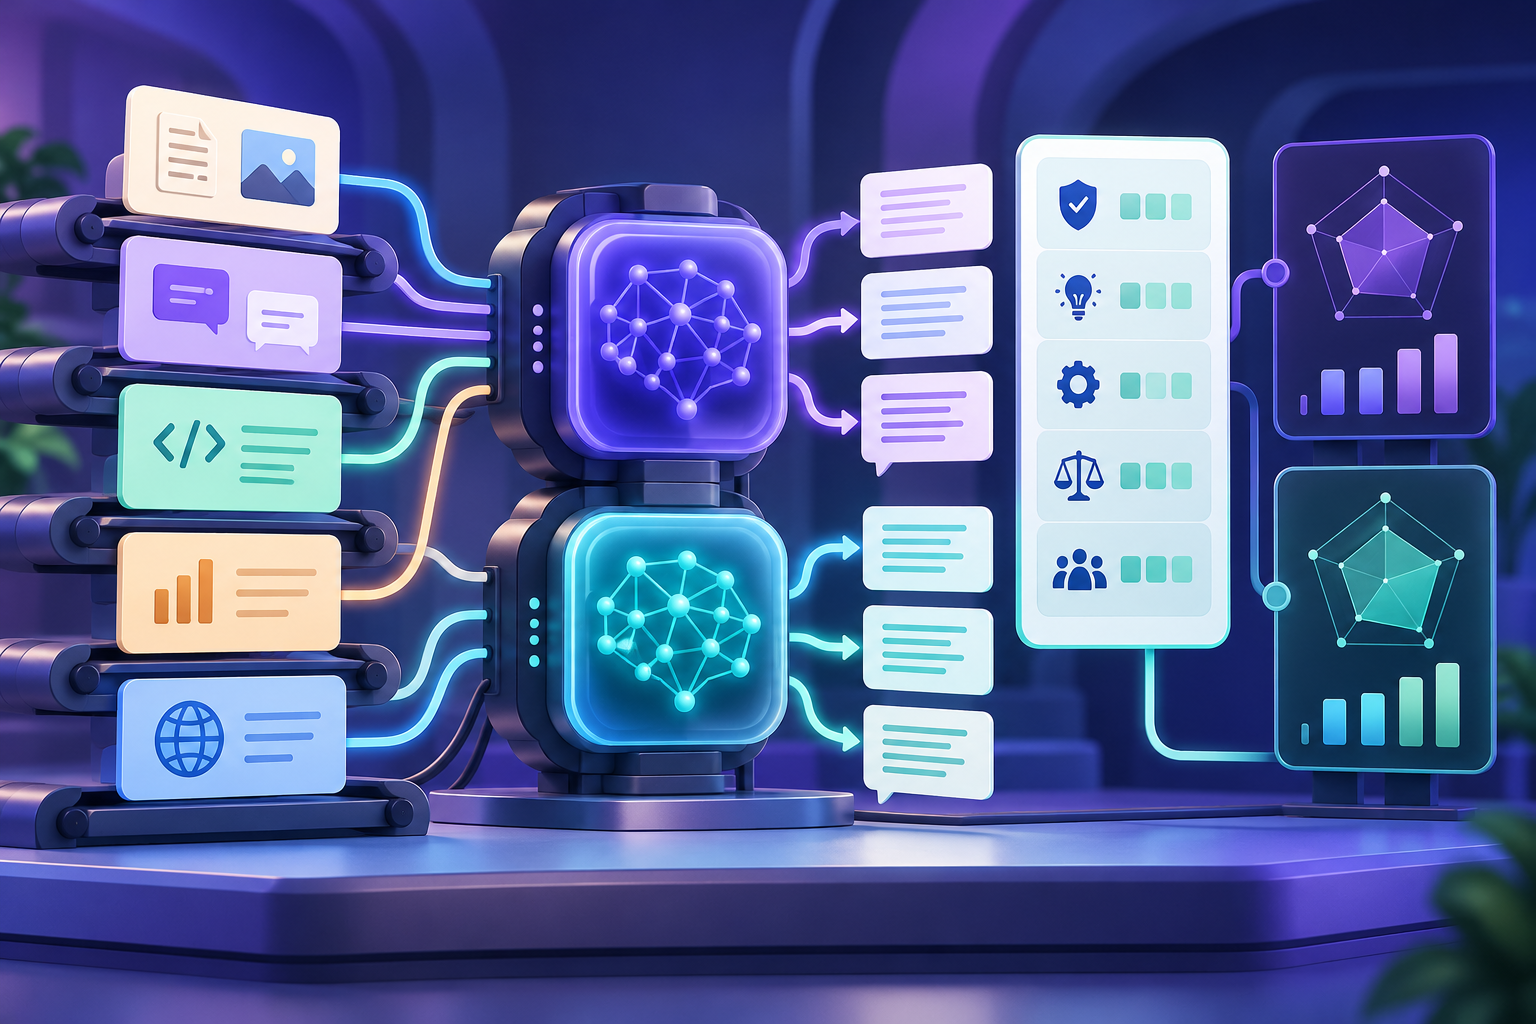
Run the same cases against the current and candidate versions. Record the model, prompt, tools, retrieval configuration, and relevant generation settings. Compare per-case outcomes as well as the overall score; a small average improvement can hide a critical regression in one important task category.
When outputs are stochastic, repeat selected cases or use a stable evaluation configuration. Save the actual outputs, not only a pass rate. A failing example is often the fastest way to understand why a change behaved differently.
When a user reports an issue, remove identifying data, reproduce the behavior, and add a test case before fixing it. This turns a one-off correction into lasting coverage. Tag the case by failure type—unsupported answer, wrong format, missing context, tool error, or privacy boundary—so that later results show which behavior is improving or regressing.
Do not let the test set grow without review. Retire obsolete cases, keep high-impact failures, and check that the examples still represent the product’s actual use. A hundred duplicated tests do not make a better evaluation than twenty well-chosen ones.
An evaluation score cannot tell you whether the feature is useful, safe, or worth its cost by itself. Combine test results with product feedback, latency, operational errors, and human review. If a candidate improves answer completeness but increases unsupported claims, the trade-off needs a product decision rather than a single aggregate score.
A small evaluation suite is valuable because it makes changes visible. It lets a team ask, “What improved, what got worse, and on which examples?” before a prompt or model update reaches users.
You might also be interested in reading these related topics